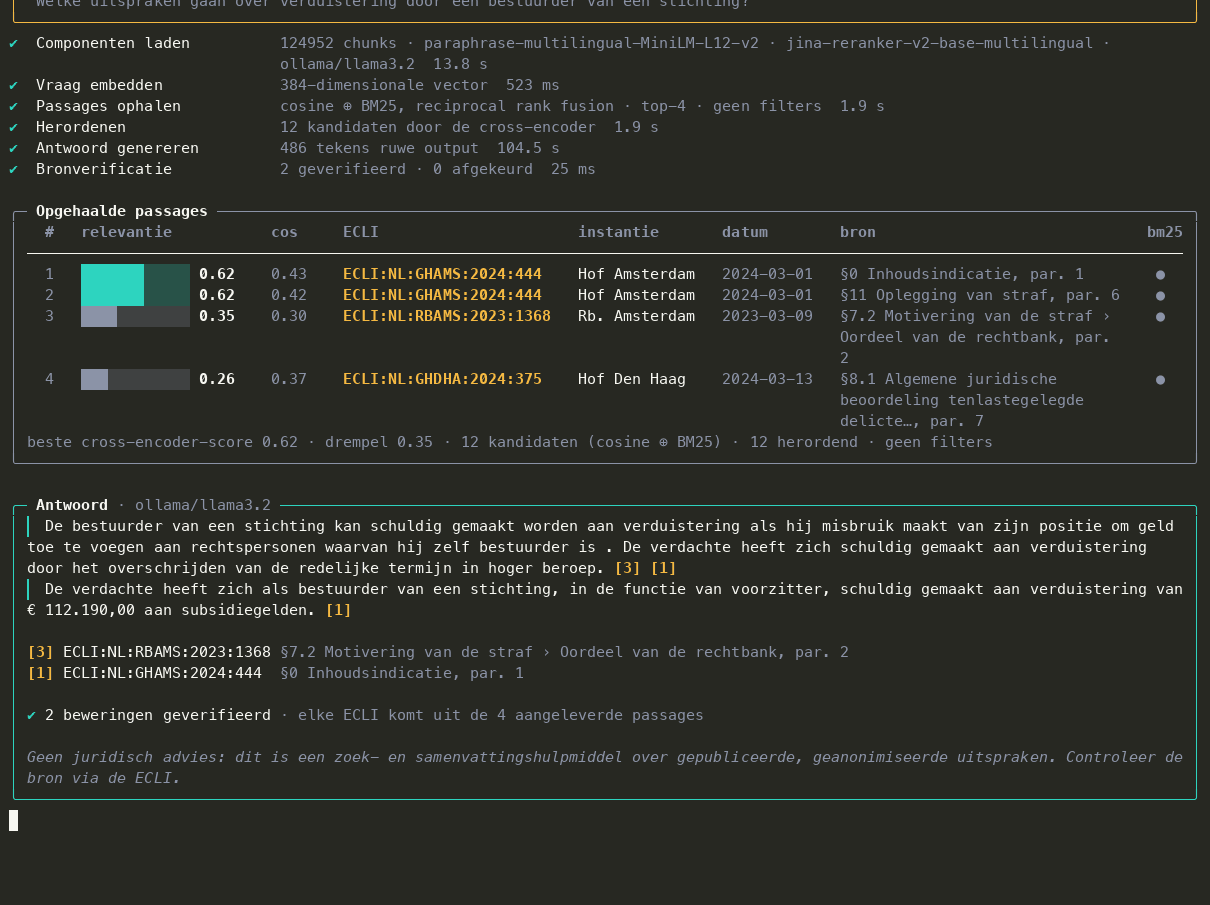
RAG over 1,906 Dutch criminal-law rulings with one rule: no source, no answer. Every claim ends in an ECLI, section and paragraph — and that reference is checked in code, not requested from the model.
Building a RAG demo is an afternoon's work: read in documents, make embeddings, fetch top-k, paste into a prompt. The problem isn't the pipeline but what comes out of it. A language model that is handed four passages and asked for an answer with sources almost always produces something that looks correct. An ECLI that doesn't quite exist, a paragraph number that points nowhere, a claim that is true but isn't in the supplied text — you can't tell the difference without checking.
In criminal law that difference is the whole point. So this project is turned around: not “how do I get the model to cite properly”, but “what can I verify hard afterwards, and what do I throw away when it doesn't hold up”. A claim without a reference doesn't make it into the answer. An ECLI that doesn't occur in the retrieved passages doesn't make it into the answer. And if the best passage stays below the relevance threshold, the model isn't called at all.
100%, by construction
89%
93%
1,906 rulings
Why this project
I wanted to know where the line runs between “a RAG system that demonstrates” and “a RAG system whose output you would dare to forward”. That line isn't at the retrieval part — the recipes there are known. It's at the question of what happens when the model says something that doesn't come from the sources.
Rechtspraak.nl publishes all rulings as open data, anonymised, with structured XML. That is a corpus where answers are objectively verifiable: an ECLI exists or it doesn't, a paragraph is there or it isn't. Exactly the kind of domain where you can build a control mechanism that is more than a feeling.
Architecture
The system splits into two halves that only touch each other through the index. The offline half builds the corpus, the online half answers one question, and in between sits a single file.

Three parts, each testable on its own
01
The offline half
Runs once per corpus extension. A client queries the Open Data search feed by date and area of law, paginates and fetches one XML per ECLI — rate limited, with backoff, resumable. The parser turns that into one Uitspraak (ruling): court, date, areas of law, procedures, case number, statutory references, summary and numbered sections with numbered paragraphs. The chunker cuts those into pieces that never cross a section boundary, and the embedder turns them into vectors.
02
The online half
Is one question long. The retriever fetches candidates, the cross-encoder reorders them and gives each a calibrated score, the threshold decides whether the model is called at all, and verification decides what remains of the answer.
03
One storage layer
SQLite with the metadata and an FTS5 index, plus the vectors as a single float32 matrix in NumPy. One file, no service.
The one rule: no source, no answer
The rule is enforced in three places, and in none of them by the prompt.

Before, during and after generation
01
Before generation
If the best relevance score is below the threshold (0.35), the LLM is not called. “No source” is thereby a property of retrieval, not a courtesy of the model.
02
During generation
The model receives numbered passages and the instruction to give one claim per line, ending in an [n] marker. It may also answer GEEN_BRON (no source) if it judges that the passages don't cover the question.
03
After generation
Every claim passes through a chain of checks: is there a marker? Does it point to a passage that was actually supplied? Does every ECLI in the claim occur in those passages? Is the claim non-empty and not already made? Whatever fails, fails — with the reason attached, visible in the output. If nothing survives, the model gets one retry with a format reminder.
That last part is where most RAG systems stop at an instruction in the system prompt. An instruction is not a guarantee. The test suite contains a fake LLM that invents an ECLI and one that omits the references; both are rejected. And the evaluation set contains questions whose answer must be that the corpus has no source — so that path is measured, not assumed.
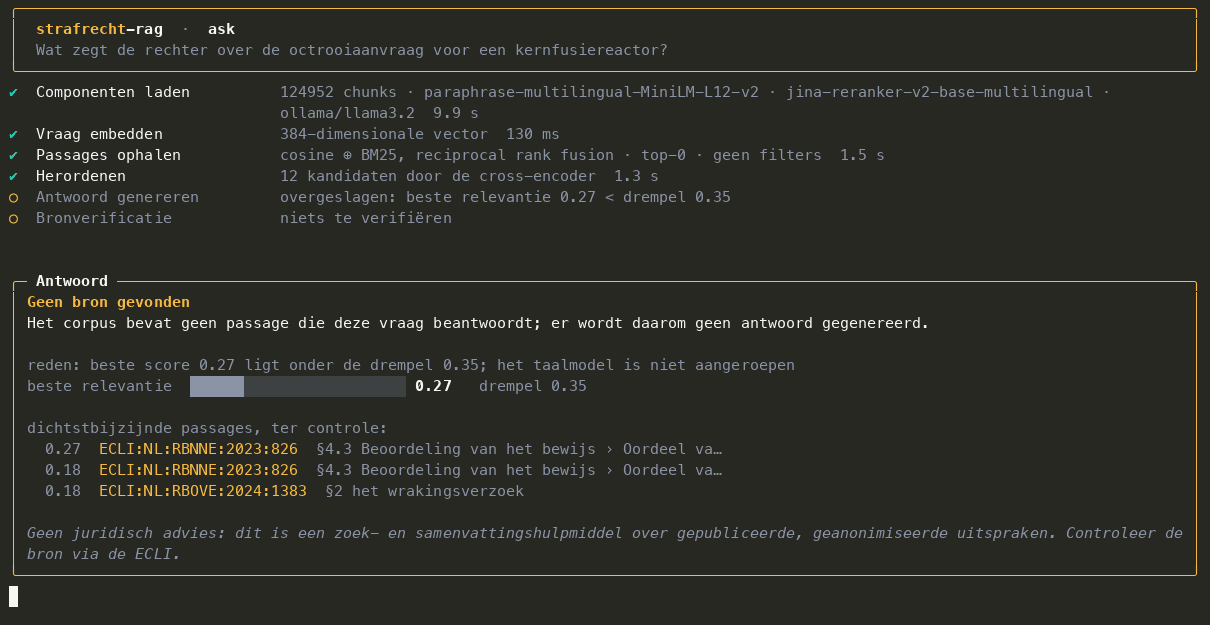
The yield is one number: claim acceptance 89%. Eleven percent of what the model produced deviated from the passages and never reached the user.
Why there is a cross-encoder
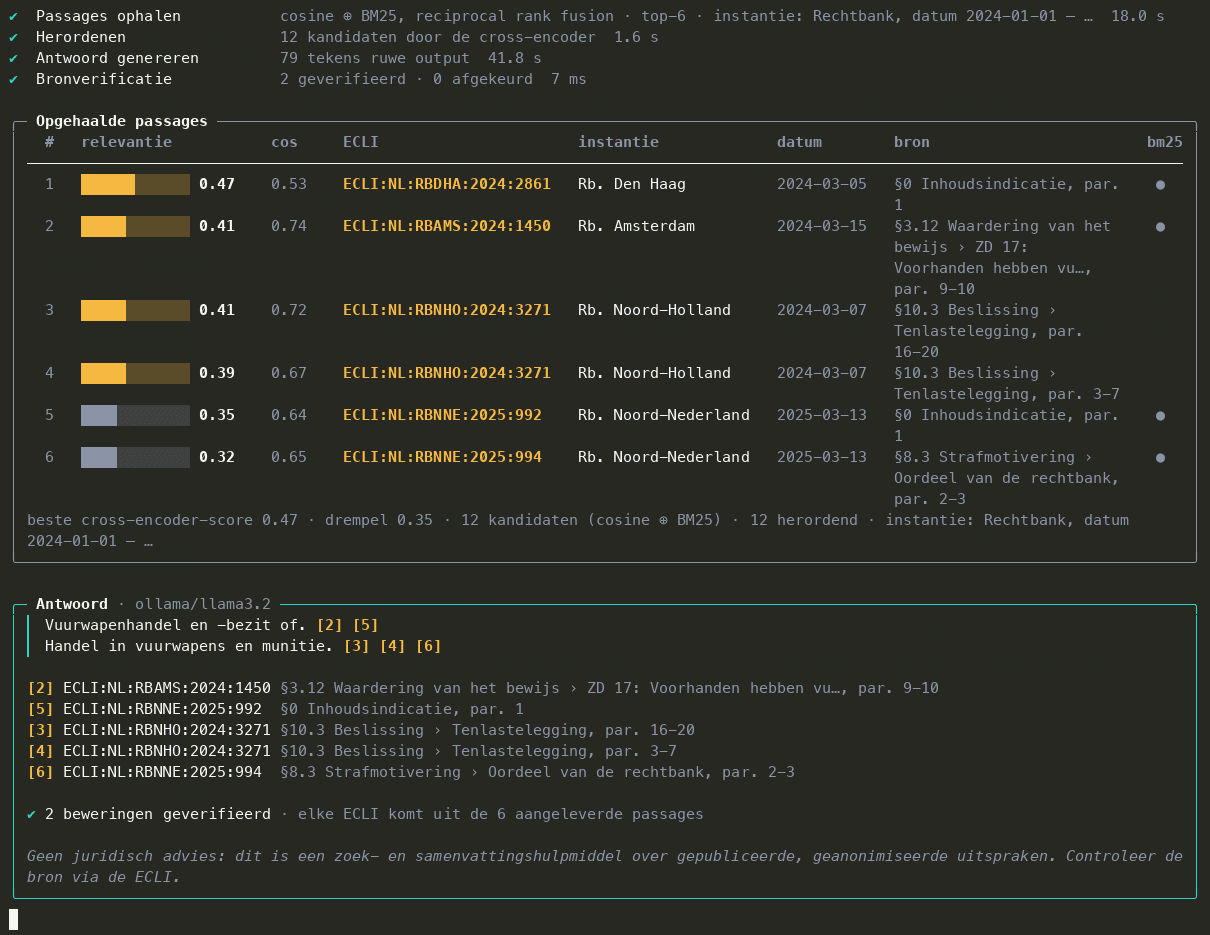
This is the measurement that decided the design. The obvious recipe is: cosine similarity, a threshold on top, below the threshold you say “no source”. That doesn't work. A bi-encoder's cosine isn't calibrated — a question that has nothing whatsoever to do with the corpus still scores around 0.6 against any legal paragraph, simply because legal Dutch resembles legal Dutch. There is no threshold value that separates “relevant” from “coincidentally the same register”.
A cross-encoder sees question and passage together and does produce a usable relevance probability. That's more expensive — but only over the top-12 candidates, and that costs a few seconds on a laptop CPU. The 0.35 threshold sits on that number, not on the cosine.
Retrieval itself is hybrid: cosine top-3k and BM25 top-3k, merged with reciprocal rank fusion (k=60). That's not a theoretical preference. Legal Dutch is exact — ECLI numbers, article numbers, place names, artikel 310 Sr — and a small multilingual embedder is bad at that where BM25 is good. On top of that, at most two chunks per ruling may enter the top-k, so one long-winded ruling can't swallow the whole context.
≈ 0.6
cosine of a completely irrelevant question against any legal paragraph
0.35
threshold on the calibrated cross-encoder score, not on the cosine
≤ 2
chunks per ruling in the top-k, so one ruling can't swallow the context
From XML to a reference
The reference the user sees — ECLI:NL:RBNHO:2024:1234, §4.2 Waardering van het bewijs › Het oordeel van de rechtbank, par. 3 — has to come from somewhere, and that is the unglamorous part of the project where most of the work went.

What it took to make that reference correct
01
Bold headings become subsections
Rulings don't put their structure neatly in tags. Position of the defence and The court's judgment often appear as a loose bold paragraph in the middle of a section. The parser splits on that: a standalone bold or underlined paragraph starts a subsection. That makes both the reference and the embedding more precise, because a chunk no longer crams two opposing positions into one vector.
02
A schema that varies by year and court
The parser matches on local element names without namespace assumptions, and is tested against recorded real rulings from both a district court and a court of appeal. One unparseable file yields one error record, never a crashed batch. Across 1,906 rulings: 0 parse errors.
03
A chunker that is pure and deterministic
The same ruling always yields the same chunks with the same ids, so re-indexing produces no duplicates. Chunks never cross a section boundary and overlap in whole paragraphs, so the paragraph numbers in the reference stay correct.
04
560 characters, 120 overlap — from the model
The embedder sees at most 128 tokens, roughly 450 characters. A chunk of window plus overlap means the part that falls beyond the window comes back as the start of the next chunk, and so still gets embedded. BM25 meanwhile does see every character, because it looks at the full text in FTS5.
The corpus
Criminal-law rulings with full text, covering the first half of March in three years (2023, 2024, 2025). Large enough for real retrieval behaviour, small enough to build on a laptop.
Three years instead of one, because a date filter only means something when there is something to filter. All courts, because the type filter (district court vs. court of appeal) would otherwise be empty.
| Rulings | 1,906 — 1,245 district court, 416 court of appeal, 132 Supreme Court, 89 Procurator General's office, 24 other |
|---|---|
| Parse errors | 0 |
| Chunks | 124,952 |
| Courts | 22 |
| Index size | 473 MB SQLite |
Evaluation
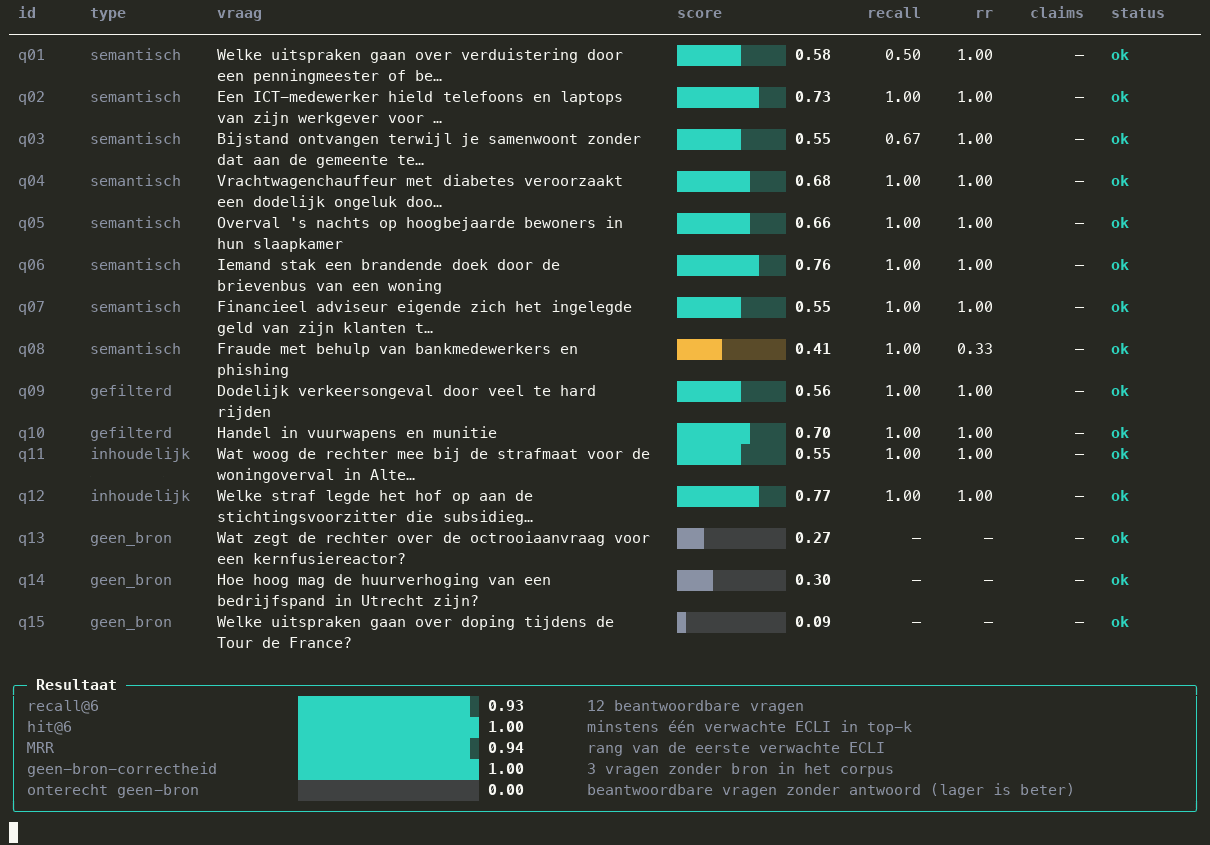
Fifteen questions in tests/fixtures/eval_vragen.json: eight semantic (deliberately phrased differently from the rulings themselves), two with metadata filters, two about the content of one specific ruling, and three the corpus has no answer to.
| Metric | Value | Meaning |
|---|---|---|
| recall@6 | 93% | share of expected ECLIs in the top-k |
| hit@6 | 100% | at least one expected ECLI in the top-k |
| MRR | 0.94 | rank of the first expected ECLI |
| source accuracy | 100% | answers in which every ECLI comes from the retrieved passages |
| claim acceptance | 89% | raw model claims that survive verification |
| no-source correctness | 100% | unanswerable questions that hit the no-source path |
| false no-source | 0% | answerable questions that are refused |
Source accuracy of 100% is not an achievement but a construction: a claim with an unknown ECLI doesn't get into the answer. The interesting number is claim acceptance, because it shows how often the model would have strayed from the passages if nobody had been watching.
The retrieval metrics need no LLM. The generation metrics were measured with ollama/llama3.2, locally.
Design choices
A few trade-offs I thought about the longest.
01
SQLite + NumPy instead of a vector database
At tens of thousands of vectors an exact scan takes a handful of milliseconds. FTS5 throws in BM25 for free, the whole thing is one file, no service runs alongside it, and no platform-specific wheels are needed — which mattered concretely, because LanceDB and recent onnxruntime have no Intel Mac wheels. An ANN index would trade exactness for speed here without any speed to gain.
02
A local, quantised ONNX embedder
paraphrase-multilingual-MiniLM-L12-v2 via fastembed: 118M parameters, about 13 chunks per second on a laptop CPU. Larger models (e5-large, bge-m3) were an order of magnitude slower on this machine for gains the evaluation didn't show. It sits behind an Embedder interface, so swapping is configuration.
03
Three LLM backends, one of them without a model
Ollama is the default (no key needed), Claude is optional, and there is an extractive backend that simply quotes the best passages verbatim. That third one isn't for show: it lets the whole chain, evaluation included, run without loading a model anywhere. And it goes through the same verification as the other two.
04
Everything behind an interface, everything fakeable in tests
FakeEmbedder (hashed bag-of-words), FakeLLM, FakeReranker, recorded XML fixtures. 93 tests, and CI runs without network, without a model download and without an LLM. That's not a purity principle but speed: the test suite finishes before you've switched tabs.
What this project shows
The hard question in RAG isn't “how do I retrieve the right pieces” but “what do I do when the model says something that isn't there”. Verification is a design choice you have to make deliberately — and then measure.
Not legal advice. This is a search and summarisation aid over published, anonymised rulings; check every source via its ECLI on rechtspraak.nl.
Data source: Rechtspraak.nl Open Data — only the published, anonymised text; nothing is enriched and nothing is de-anonymised.