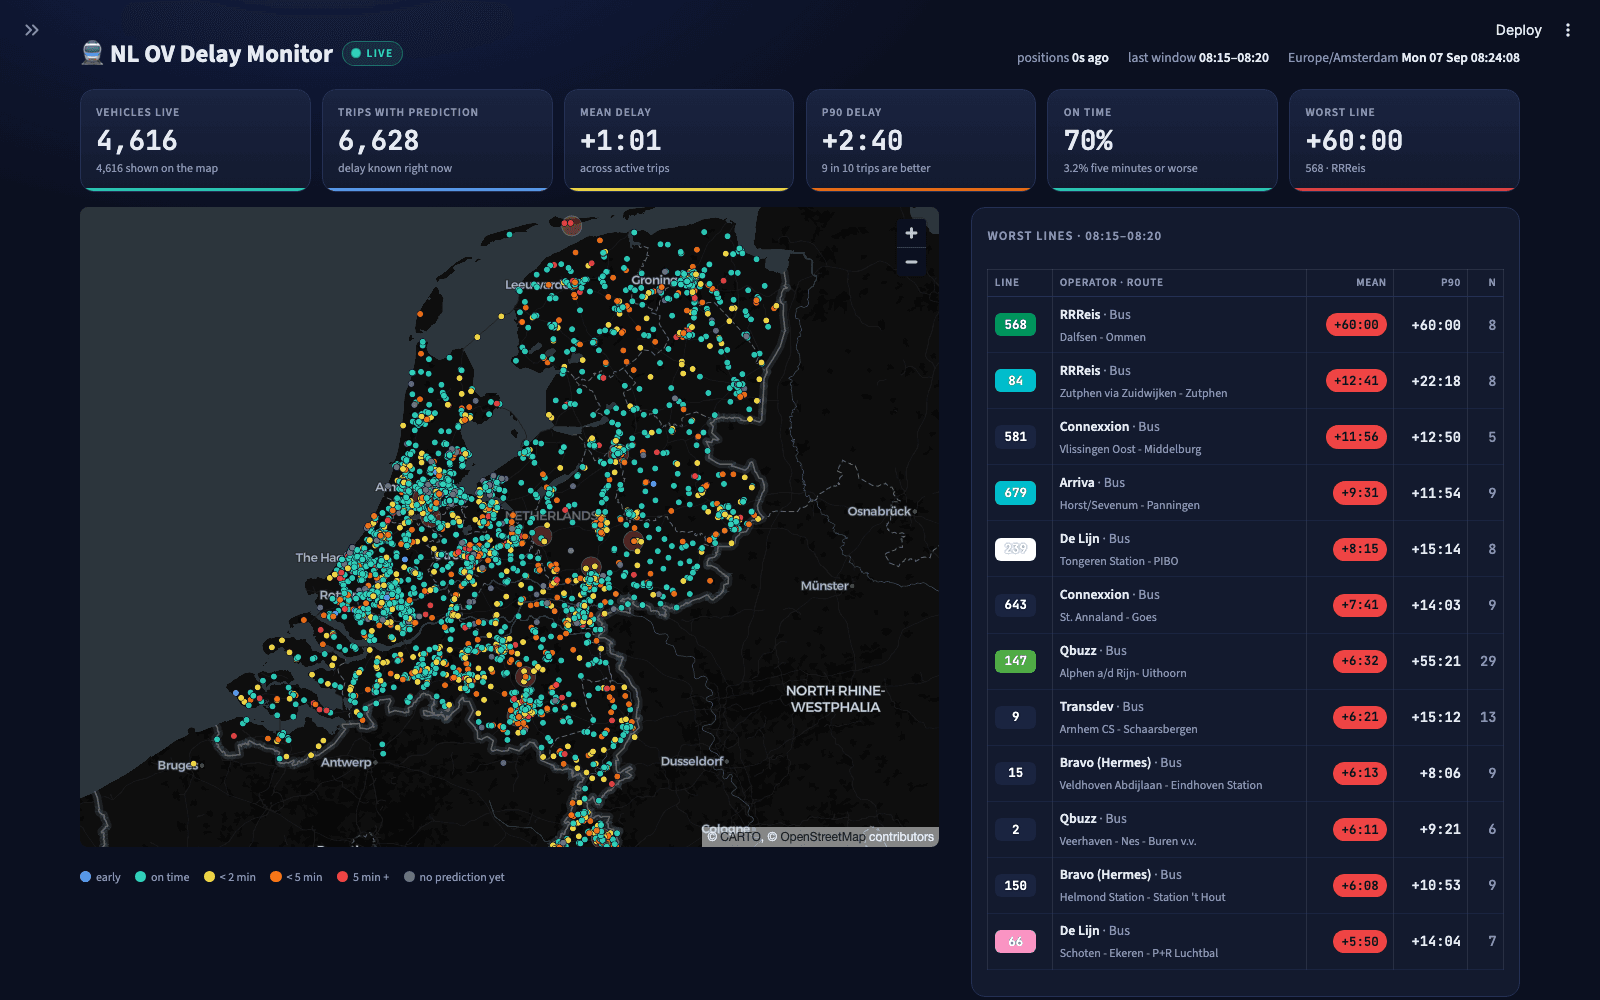
Every vehicle in Dutch public transport, streamed live — from GTFS-realtime feed to a map of the whole country, with the correctness guarantees to go with it.
Two files on an open endpoint contain, every minute, where roughly 4,900 vehicles are and how late they are. Turning that into a dashboard is an afternoon's work. Turning it into a pipeline that runs 24 hours a day, produces the right numbers after a crash, doesn't silently lose broken messages, and lets you recompute an hour from the past — that is a different project.
This is that second project. A producer that turns snapshots into change events, Redpanda as the bus, a stream processor with tumbling windows and per-partition watermarks, a raw archive in MinIO you can replay from, Postgres as the serving layer and a live map on top. Thirteen containers, one make up, no accounts and no keys.
176 messages/s
5 min · 4 dimensions
106, no infra
Zero, fully local
Why this project
You don't learn streaming from a tutorial with a for loop over a list. The interesting things only happen once real time is involved: events arriving late, partitions drifting apart, a process falling over between two writes, a feed that doesn't follow its own documentation.
I wanted to run into those things instead of reading about them. A nationwide, public, always-on data source forces that — and produces something you can show at the same time.
Architecture
The chain runs from left to right. The producer fetches two protobuf feeds, parses them into a versioned event contract and publishes to two Kafka topics. Two independent consumer groups read along: the processor computes windows and writes to Postgres, the archiver writes the raw bytes to MinIO. A sidecar loads the static GTFS reference data daily. The dashboard sits on Postgres, Prometheus scrapes everything.

Two architectural choices determine the rest of the design
01
The broker is a buffer, not an archive
Retention on the raw topics is 24 hours. What you still need a month from now lives in MinIO, as bytes — not as parsed events. That distinction looks small and isn't: because the archive keeps bytes, you can run a new decoder over it later. Had you stored parsed events, you would have frozen that day's interpretation forever.
02
Two consumer groups instead of one service doing both
Archiving and processing have different failure modes and different speeds. If MinIO is briefly gone, the processor has to keep going — and the other way round.
The problem the producer solves
Both feeds are FULL_DATASET snapshots: every minute the complete picture comes by again. Publish that directly and you're at around 700 messages per second that are mostly repetition.
So the producer diffs every snapshot against the previous one and publishes only what changed. In the morning rush that suppresses about 45% of the entities per poll. To stop a train that has been sitting at +5:00 for twenty minutes from disappearing from the statistics, a heartbeat goes out every sixty seconds. The result: five to twenty times fewer messages, with identical window figures.
45%
of entities per poll suppressed in the rush hour
5–20×
fewer messages, with identical window figures
60 s
heartbeat, so a standing delay keeps counting
What the feed doesn't document
Entity ids like 2026-09-06:GVB:13:13605 contain the operator code, which appears nowhere else in the message — so it's parsed out of the id.
VehiclePosition carries no delay; that lives in TripUpdate.
Ghost vehicles roam the feed: a bus STOPPED_AT the same spot for eleven days, and one vehicle reporting from 29 minutes in the future.
Positions older than ten minutes or more than a minute ahead are dropped.
All of those cases are captured in recorded protobuf fixtures in the repo: 140 KB that pins every parser test to reality.
Windows, watermarks and late events
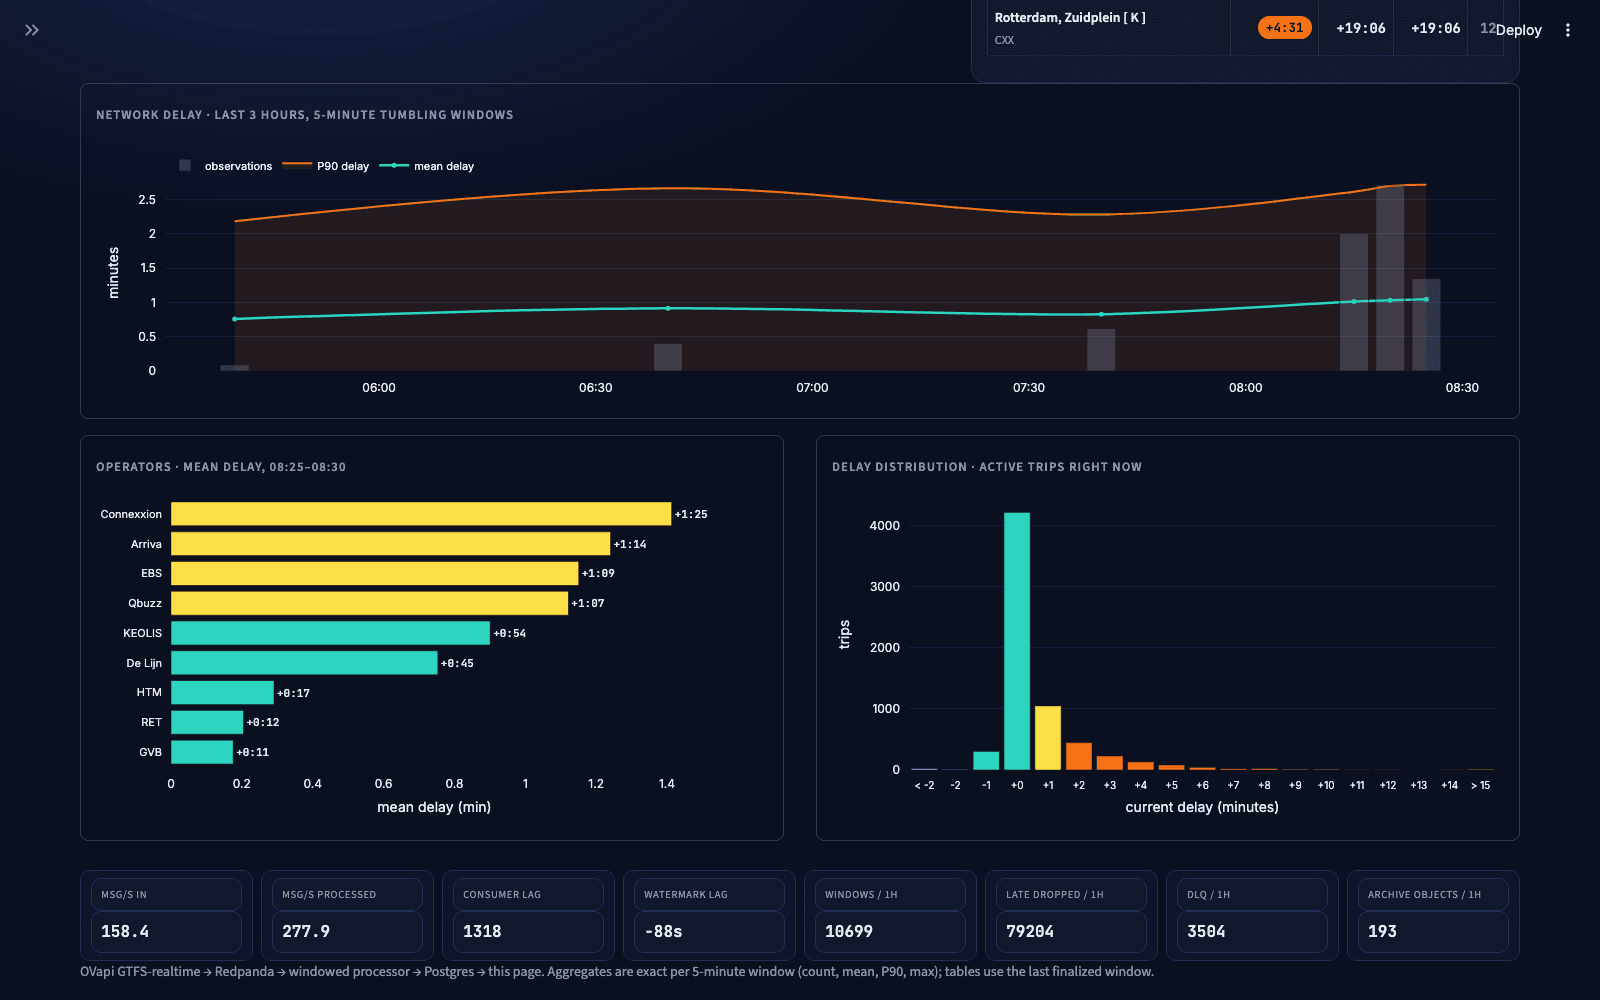
The processor computes five-minute tumbling windows, aligned to the epoch, over four dimensions at once: line, stop, operator and network. Per window: count, mean, exact P90, max and min.
The watermark is where the real work is. First version: one global maximum over all events received. That worked fine until a forty-minute catch-up came along — the six partitions were consumed at different speeds, the fastest pulled the watermark ahead, and 169,000 perfectly normal events from the slower partitions were labelled “late” and dropped.
Events behind the watermark are counted and dropped. That's an explicit trade-off: bounded state and exactly one emission per window, in exchange for ignoring anything more than two minutes behind. In practice that number is zero, because the event time is the feed's own generation time and it increases monotonically.

Three lessons that shaped the watermark
01
Per partition, not global
The fix is what Flink does: a watermark per partition, and the minimum of those counts. That way a fast partition can never invalidate the events of a slow one.
02
A silent partition doesn't count
Otherwise a partition that stops sending holds the watermark back forever and no window ever closes again. After 120 seconds of silence a partition is left out until it speaks again.
03
And when the whole country goes quiet
Between 01:00 and 05:00 there are twenty to thirty night buses running. Without intervention the last window never closes, because no event arrives to push the watermark forward. After ninety seconds of silence the processor advances the watermark on the wall clock.
At-least-once, made safe by idempotence
Exactly-once delivery is deliberately not pursued. The cheaper guarantee gives the same answer, without transactional machinery.
The order is: process, upsert the finalised windows, and only then commit the offsets. If the process dies between those two steps, the broker redelivers the same messages, the processor recomputes the same window from the same events, and writes it under the same key. The primary key of delay_aggregates is (window_start, dimension, dimension_id) — the upsert replaces the row with identical values instead of adding to it. Double counting is therefore impossible.

Two details make that watertight instead of roughly right
01
Offsets never run ahead of open windows
Per partition the processor keeps the consumed (offset, window_end) pairs in arrival order, and commits one past the longest contiguous prefix whose windows are all closed. If a message halfway through still belongs to an open window, the commit stops there — even if finalised windows sit behind that message. Everything in an open window is redelivered after a crash and rebuilds that window from scratch.
02
The watermark is seeded from Postgres at startup
max(window_end) makes redelivered messages that belong to an already-written window count as late, instead of a partial window being written over a complete one. That seed is clamped to the wall clock — a lesson from practice: once, a replay that was still running seeded the watermark into the future, after which 130,000 good events were dropped.
test_duplicate_delivery_does_not_double_count_in_real_postgresapplies the same finalised window twice against the real database and checks that there is one row, with the original count.
When things go wrong
Anything that can't be parsed (producer) or decoded (processor) goes to dlq.<source_topic> as the original bytes, with headers for stage, source topic, partition, offset, error, timestamp and schema version. The main loop never blocks.
One detail you only discover by running it: parse errors repeat every minute, because the feed simply sends the same broken entity again. Without a countermeasure your DLQ fills up with the same message a thousand times. So the producer dead-letters each unique combination of entity and reason once.

Two recovery paths
make replay-dlqThe failed step again, with the current code
A parser fix, a new schema version. Whatever now succeeds goes back into the source topic with a replayed_from header; whatever is still broken stays and is summarised per reason.
make replay FROM=… TO=…Recompute a time range from the MinIO archive
Replay runs through the same Pipeline class as the live consumer. No second implementation of the windowing logic — if there were, you'd be testing two things and trusting one.
Measured: 122,364 archived messages from twelve minutes of morning rush, recomputed into 11,323 windows in about ten seconds.
Schema evolution
SCHEMA_VERSION is in the body of every message and in a Kafka header, so a consumer can route on version without parsing the body. Backwards-compatible changes — an optional field with a default — don't bump the version. Removing, renaming or retyping a field does.
common.serde keeps a decoder per supported version, and the processor accepts the current and the previous one. An unknown version is a SchemaError — so the DLQ, never a crash. And because the archive keeps bytes rather than events, a new decoder can always be run over the history.
Rolling out a new version without breaking the pipeline
01
First the processor that reads v1 and v2.
02
Then the producer that writes v2.
03
After 24 hours of retention with no v1 in circulation, the old decoder can go.
What it does in practice
Measured on a 2019 MacBook Pro with the whole stack in Docker Desktop, nationwide feed, no operator filter. make throughput pulls these figures straight from Prometheus.
| Messages in, average | 176 per second (peak minute 347) |
|---|---|
| Vehicles in the feed per poll | 3,625; the snapshot differ suppressed 45% |
| Windows finalised | 2,739 per five minutes, 6,994 open at once |
| Consumer lag | p50 zero; at most 3,806 right after a restart, caught up within a minute |
| Watermark lag | 170 seconds — 120 s allowed lateness plus ~50 s feed cadence |
| Batch processing p95 | 0.18 s for a batch of 2,000 messages, including the state upserts |
| Raw archive | 718 objects, 30 MB gzip per hour in the rush; ~1 MB/hour at night |
Two things you only learn by actually letting it run through a night
01
Rush hour and night differ by a factor of a hundred
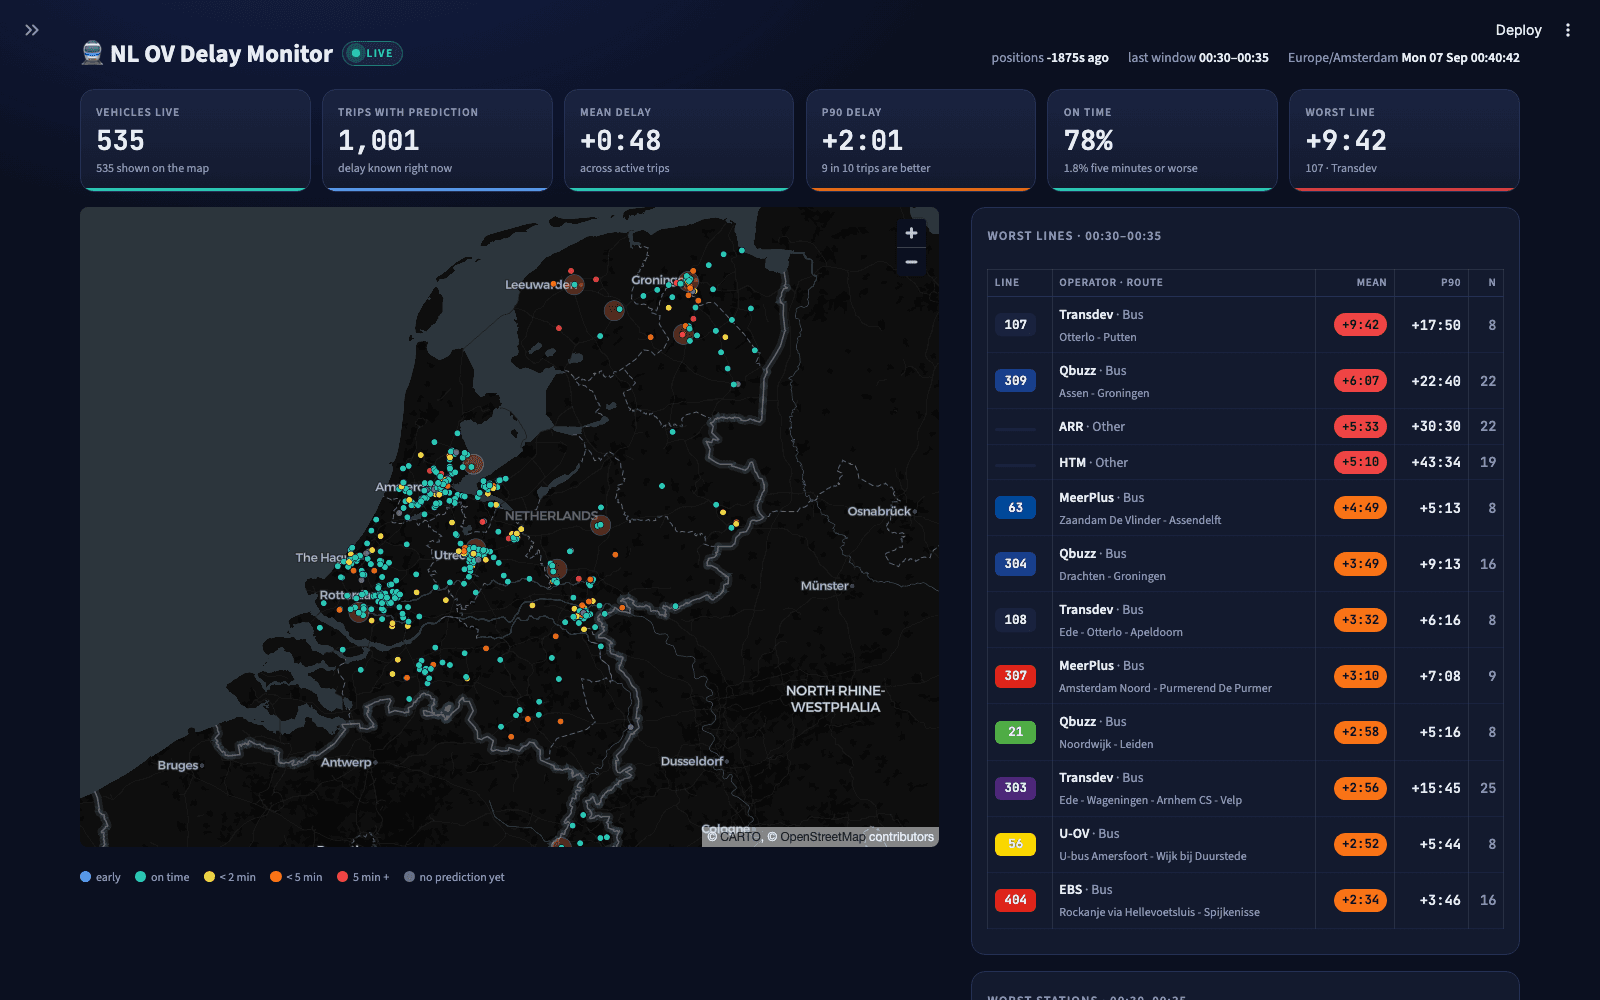
At half past eleven at night it's 50 to 110 messages per second and 1,400 vehicles; at four in the morning two messages per second and twenty buses — and the dashboard says so honestly instead of faking movement.
02
A sleeping laptop is not a pipeline outage
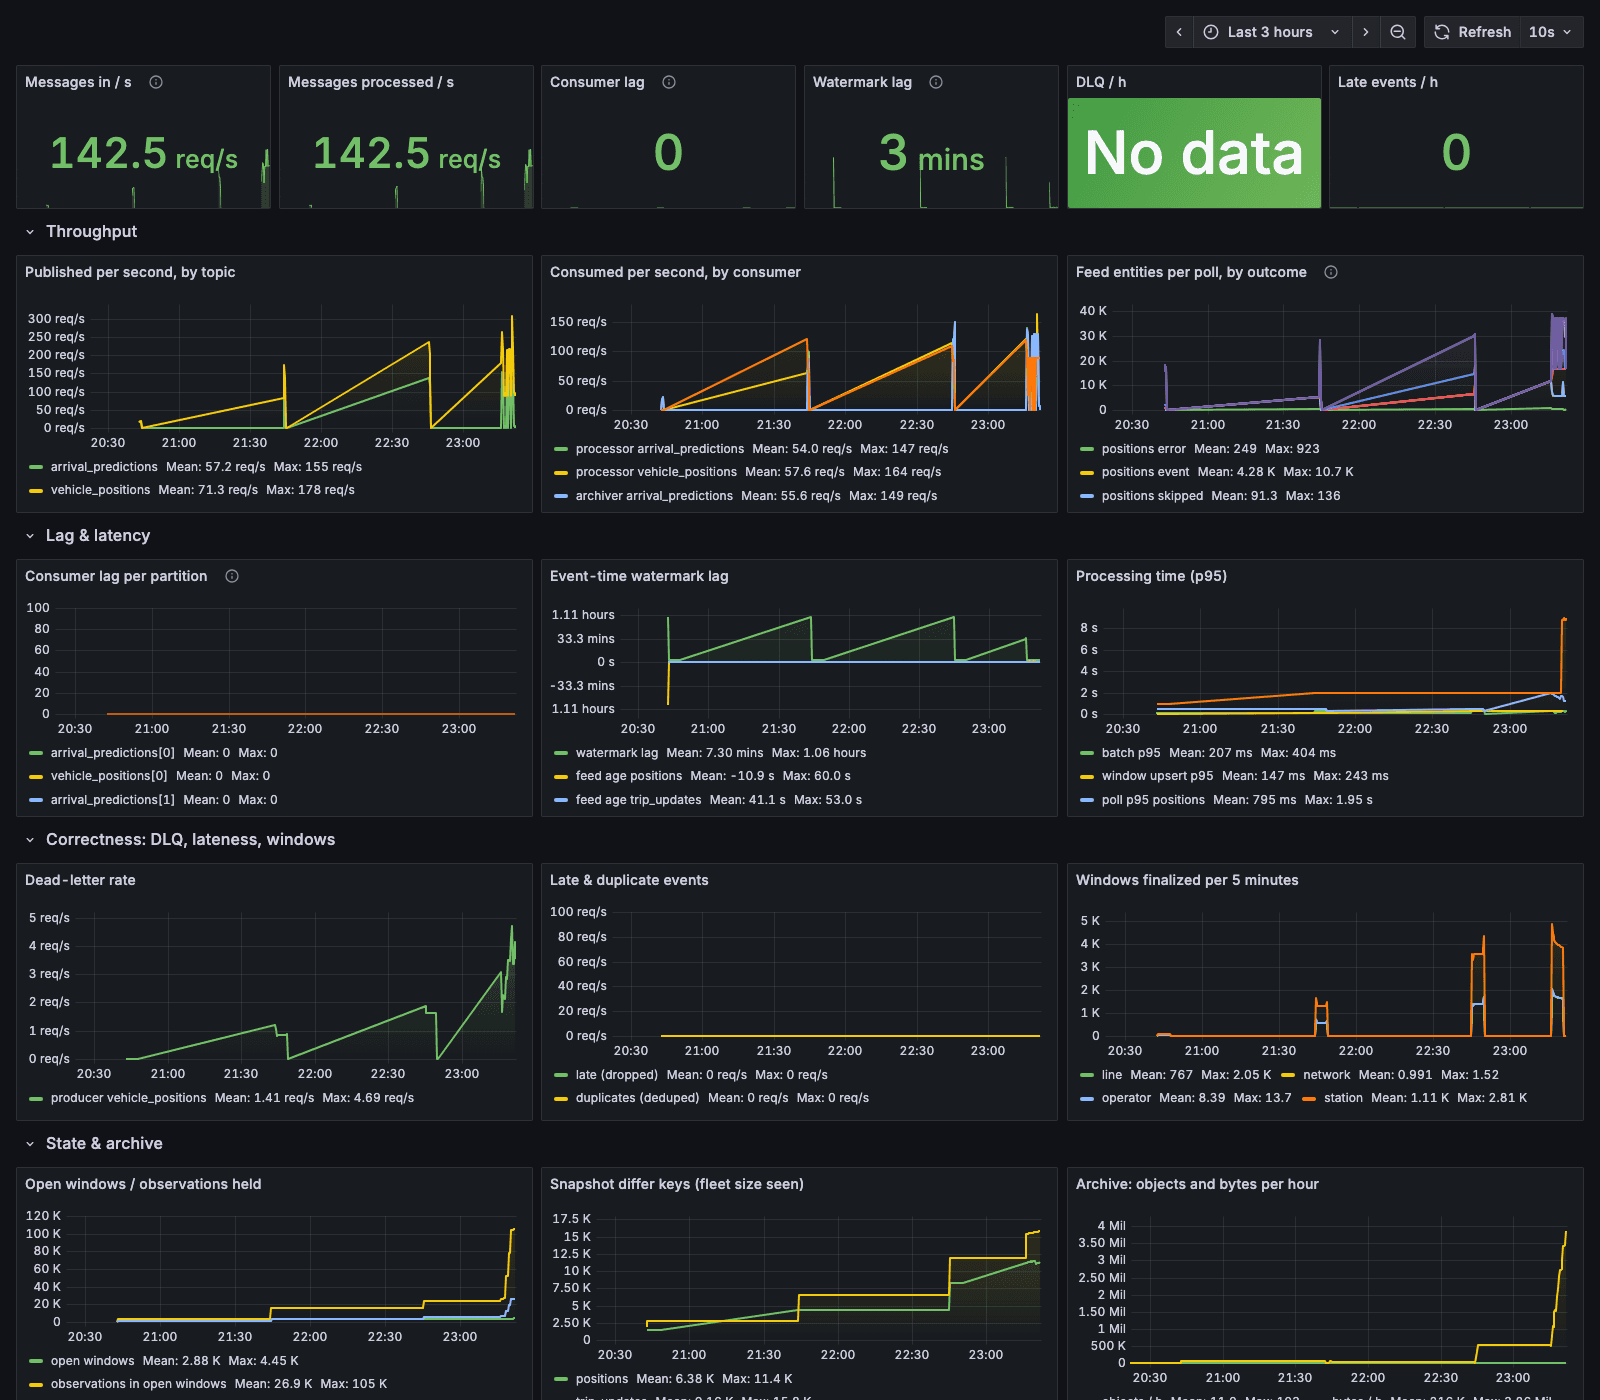
But it looks exactly like one in Grafana: macOS wakes up for 45 seconds of maintenance every hour, which produces one tall spike per hour and a watermark lag of half an hour. make keep-awake is in the runbook now.
Design choices, briefly
A few trade-offs I thought about the longest.
01
Pure-Python windowing engine, no Kafka imports
The window logic knows no broker. That makes the tests deterministic with synthetic sequences — including a window computed by hand — and the same engine also runs the replay.
02
Exact P90 instead of a t-digest
A few thousand observations per window per key makes nearest-rank free, and it makes a hand-computed test possible. At real scale this is the part you'd replace; the accumulator interface doesn't change for it.
03
Extra dimensions instead of deriving
You can't derive the network P90 from the per-line P90s. Four dimensions cost one dict insert each, so they're simply tracked separately.
04
Static GTFS via COPY and an atomic table swap
The 220 MB zip goes straight into COPY, into staging tables that are then swapped in a single transaction. Readers never see a half-loaded set. A daily sleep loop, no Airflow — this is a cron sidecar, not orchestration.
05
Python instead of Spark Structured Streaming
The simplest thing that demonstrates windowing correctly. The switch is a documented migration, not a precondition.
Testing and observability
make test runs 106 unit tests without any infrastructure: the parser against recorded feeds — including a mixed-quality fixture and one of pure nonsense — serde round trips and every SchemaError path, the snapshot differ, window assignment, lateness, duplicates, per-partition watermarks, the hand-computed window, sink idempotence, DLQ headers, the offset ledger and the dashboard's SQL invariants.
make test-integration runs against the live stack: the duplicate-delivery test on real Postgres, the GTFS loader's atomic swap, the dashboard queries. CI runs lint and unit tests; the integration tests stay local.
Prometheus scrapes every service and Redpanda itself. Grafana ships with a provisioned dashboard of 26 panels — throughput, consumer lag, watermark lag, DLQ rate, late events, processing time, state size and archive volume. make inject-bad publishes two poisoned messages; within ten seconds you see them in make dlq-peek, on the Grafana panel and in the dashboard's health strip.
What this project shows
Or shorter: a pipeline where I can explain what happens when it falls over.
Data source: OVapi GTFS-realtime, open access without a key